National Policy Performance & Proportional-Parity Benchmark
Proved headline metric systematically overstates national policy performance; designed proportional-parity benchmark across 210 categories nationwide.
Project Overview
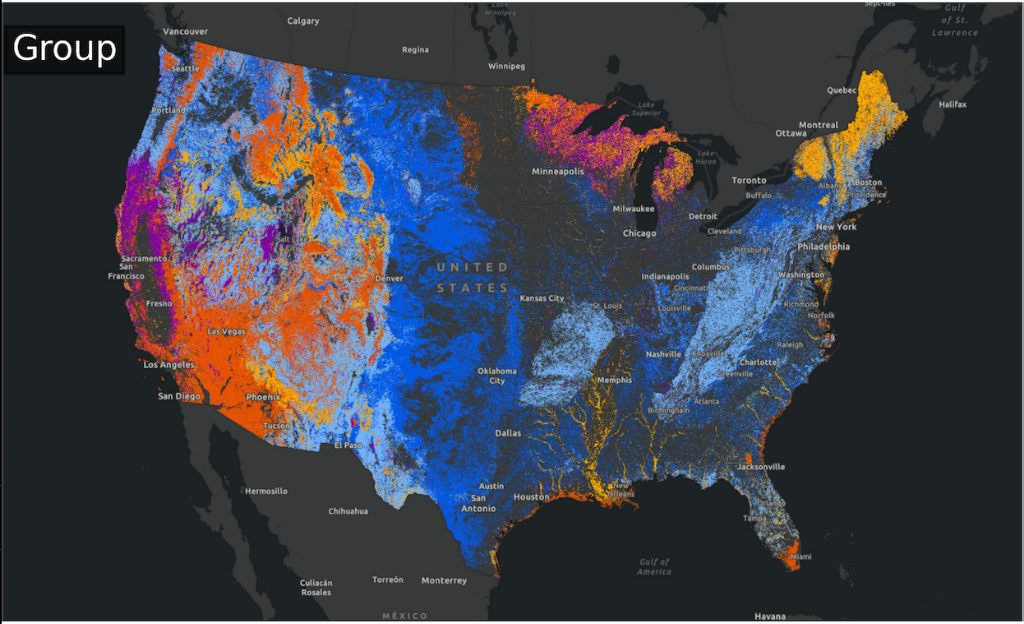
Determined which metric faithfully represents national policy performance to external audiences: proved the headline statistic in widest official use systematically overstates it, and designed the proportional-parity benchmark replacing it across 210 classification categories nationwide. Quantified how metric definition drives externally reported results: the permissive tier supplies 70% of the headline number, and a published policy target appears met for 63% of units under the loose definition against 19% under the strict one. Audited a widely cited published result and proved its reported intercept and crossover point were algebraic identities rather than empirical findings, retracting an inference that had already propagated into downstream policy debate. Own the Python and R pipelines reconciling four heterogeneous federal data sources with automated QA.
My Role
Graduate Research Scientist & Technical Lead. Owned research design, proportional-parity benchmark construction, algebraic audit, and automated QA validation.
Tools / Stack
Project Details
Implementation Roadmap
Development Process.
Reconcile four heterogeneous federal data sources with automated QA so every externally reported figure traces to source.
Reproduce all 21 published statistics from the prior national assessment as a validation gate.
Audit published literature equations, identifying algebraic identities masquerading as empirical findings.
Design proportional-parity benchmark algorithms across 210 ecosystem categories nationwide.
Structure two-tier quality evaluation isolating permissive definitions that overstate outcomes (70% headline contribution).
Case Study Analysis
Challenges & Outcomes.
Official headline figures often obscure metric definitions, creating discrepancy risks where 63% of units appear compliant under permissive standards versus only 19% under strict ones.
Designed the proportional-parity benchmark and a rigorous two-tier quality framework backed by automated Python and R validation pipelines.
Proved systematic overstatement in official metrics, replaced legacy benchmarks across 210 categories, and retracted flawed mathematical inferences from downstream policy debate.